A hands-on tutorial for building data monitoring integration in Python, Java, and Go — covering proxy configuration, retries, concurrency, metrics, and language-specific ops pitfalls.
A framework for evaluating IP pool quality beyond raw count — survival period, deduplication, scheduling, and task isolation determine enterprise scraping success and cost efficiency.
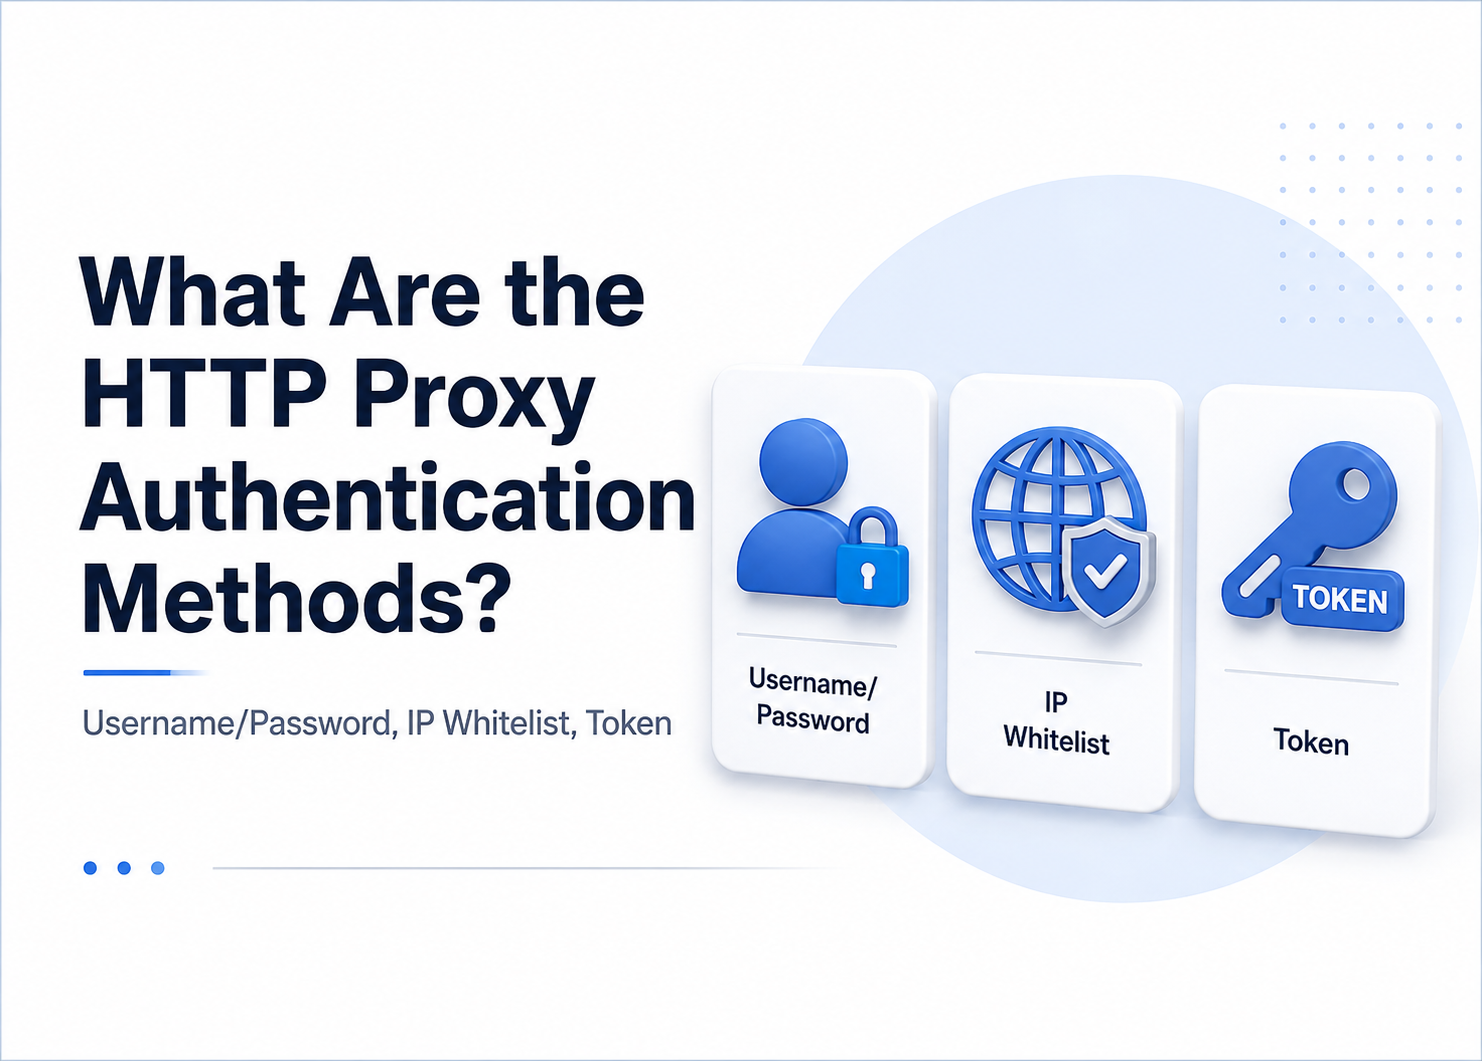
Choosing the right HTTP proxy authentication method isn't just a connection detail — it shapes your integration flexibility, ops cost, and team-level access control.
A tunnel proxy provides a fixed entry with cloud-rotated exit IPs, eliminating the need to maintain your own proxy pool for high-frequency, large-scale, sustained data scraping.