Why Shouldn't You Buy IP Proxies Before the Project Starts?
Whether an IP proxy fits the project depends on whether business requirements match the proxy mechanism — not on resource counts or package names.
The same kind of IP proxy can face very different requirements across projects:
- Public web information scraping cares more about geographic coverage, request stability, and bulk extraction methods.
- Sentiment monitoring cares more about sustained runtime, connection stability, and data refresh frequency.
- Bidding data organization cares more about access region, task cycle, account permissions, and result traceability.
- API integration or cross-region network testing cares more about protocol compatibility, fixed exits, and authentication method.
- Multi-environment deployment cares more about permission isolation, failover, and logging.
Without confirming these conditions, direct purchase can lead to:
- Needing a fixed exit but choosing a resource that changes with every request.
- Needing to hold a session long-term but choosing a short-lived resource.
- Business using HTTPS or SOCKS5 but only testing HTTP.
- Project needing overseas regions but only validating domestic nodes.
- Comparing only unit price at procurement without reconciling billing units, validity, and overage fees.
- Not retaining test logs, making it impossible after launch to tell whether issues came from the proxy, the target service, or the local program.
So the first question in selection isn't "which proxy is cheaper" — it's writing down the access conditions the project needs.
What Questions Do IP Proxy Requirement Confirmations Need to Cover?
Requirement confirmation should cover at least eight areas: business goal, access target, region, protocol, concurrency, duration, billing, and compliance.
Start with the requirements table below to avoid missing critical conditions.
| Confirmation Dimension | Questions to Answer | Impact on Selection |
|---|---|---|
| Business goal | Is the proxy for public data scraping, sentiment monitoring, API integration, or cross-region testing? | Determines product type and testing focus |
| Access target | Are you accessing web pages, public APIs, or an authorized business system? | Confirms compliance boundaries and protocol requirements |
| Region | Domestic, overseas, or specific city or country? | Determines node scope and regional filtering method |
| Protocol | Does the program use HTTP, HTTPS, or SOCKS5? | Confirms client-proxy protocol compatibility |
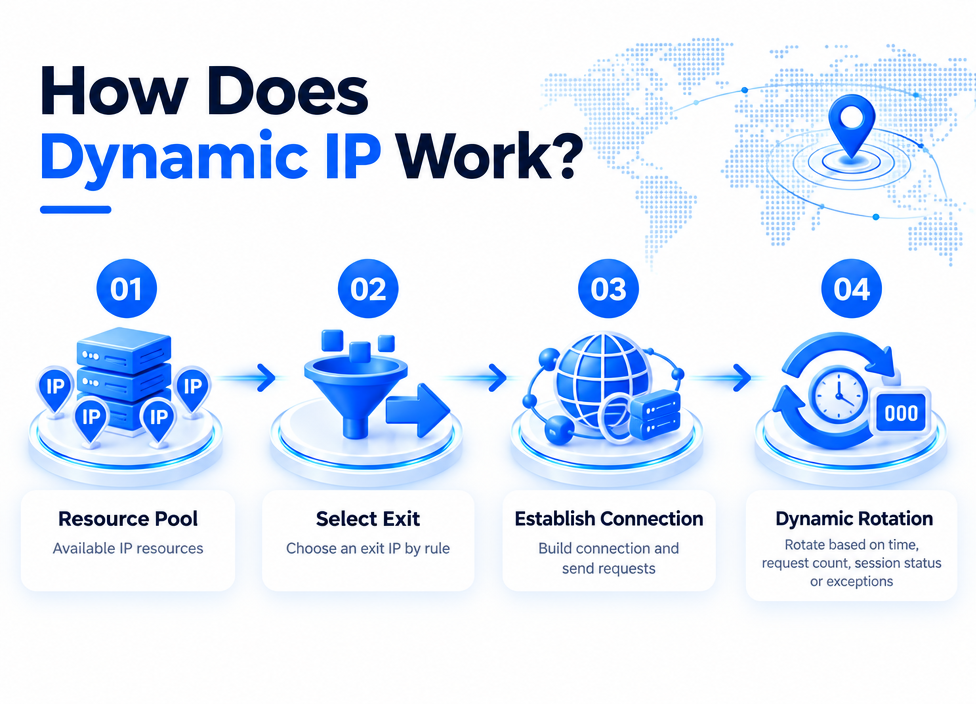
| IP rotation pattern | Rotate per request, hold by time, or fixed exit? | Determines short-lived, tunnel, long-lived, or dedicated type |
| Concurrency scale | How many threads, processes, or service instances run simultaneously? | Affects connection count, bandwidth, and resource quota |
| Task duration | Just a few minutes of testing, or continuous runtime over days or longer? | Affects IP validity, renewal, and monitoring arrangements |
| Billing method | Per request, per traffic, per time, or per resource bundle? | Affects cost accounting and budget control |
| Authentication | Username/password, IP allowlist, API key, or multiple in parallel? | Affects deployment method and permission management |
| Compliance | Does it involve personal information, sensitive data, or unauthorized systems? | Determines data scope, access frequency, and audit requirements |
Once requirements are confirmed, draft a one-page "IP Proxy Requirements Statement" containing at least:
Business scenario:
Access target:
Authorized scope:
Target region:
Protocol used:
Concurrency per instance:
Expected request volume:
Task duration:
Expected IP rotation pattern:
Authentication method:
Acceptable response time:
Failure handling requirement:
Budget and billing preference:
This statement helps technical staff test and lets procurement, product, and operations use the same evaluation standard.
Which IP Proxy Types Suit Which Projects?
Choose proxy type by IP rotation pattern, session duration, and exit stability — not by name alone.
| Type | Main Characteristics | Better-Fit Tasks | Key Items to Confirm |
|---|---|---|---|
| Short-lived proxy | IPs change on a short cycle | Short-term batch requests, temporary testing, public information organization | IP validity time, extraction method, request quota |
| Tunnel proxy | Program connects to a fixed entry; service-side handles exit scheduling | Sustained requests, server-side integration, reducing local switching logic | Concurrency limits, connection persistence, failure retry |
| Long-lived proxy | IPs stay usable for extended periods | Tasks needing a stable source or longer session | Validity period, liveness detection, renewal method |
| Dedicated proxy | Exit resources used by a single business | Tasks needing fixed exits, dedicated permissions, or isolated environments | Exit persistence, protocol support, permission isolation |
| Rotating residential proxy | Exit region and IP exhibit dynamic variation | Overseas public data scraping, regional content verification | Region filtering, billing unit, session persistence |
| Datacenter proxy | Network paths and resource management are relatively concentrated | API integration, automated testing, stable connection tasks | Network quality, protocol compatibility, fixed-exit capability |
Use this decision sequence during selection:
- Do you need a fixed exit?
If a fixed exit or fixed allowlist is required, prioritize long-lived or dedicated types. - Do you need to hold the same session for a long time?
If login state, cart state, or business sessions need to persist, confirm session-persistence capability — not just whether the IP is available. - Do you need continuous exit rotation?
If the task itself needs different regions or exits, confirm rotation cycle, switching method, and extraction API. - Are there explicit regional restrictions?
When a specific country, city, or carrier is required, make regional filtering an acceptance condition — not a post-purchase add-on. - Does it need to serve multiple systems?
If one resource needs to serve multiple businesses, confirm permission isolation, project grouping, and usage logging.
What to Prepare Before IP Proxy Testing?
Lock down the test environment, test target, and pass criteria before testing — otherwise results can't drive selection.
Prepare the following:
Test environment
- Same programming language and network library as the production project.
- Server region close to the production deployment.
- The HTTP client, browser, or business SDK planned for use.
- Preset concurrency, request intervals, and timeout parameters.
- Logs capturing request time, response status, error type, and exit information.
Test targets
Test targets should be authorized public pages, test endpoints, or business systems — don't validate unproven resources against production tasks.
Prepare at least three categories of targets:
| Target Type | Primary Test Focus |
|---|---|
| Connectivity address | Judge whether the proxy can establish a connection |
| Region-identification address | Judge whether exit region matches requirements |
| Business test address | Judge whether actual pages or endpoints return normally |
Test metrics
Don't just log "success" or "failure." Record at least:
Test time
Proxy address or resource ID
Exit region
Request protocol
Connection time
Time to first byte
Full response time
HTTP status code
Response content length
Error type
Whether a timeout occurred
Whether a connection drop occurred
If testing involves accounts, tokens, or other sensitive information, use test accounts and masked data, and limit sensitive-field logging.
How to Design a Reproducible IP Proxy Test?
Reproducible testing uses fixed targets, fixed parameters, and stepped load increases.
Execute in four stages.
Stage 1: Baseline connectivity test
Confirm the most basic network capability first:
- Connect to the test address through a single proxy.
- Log whether the connection succeeds.
- Check returned status code and response content.
- Repeat multiple times, observe whether random failures appear.
- Repeat testing across different regions or resources.
This stage mainly rules out address, port, authentication, and protocol misconfiguration — not suitable for judging long-term stability directly.
Stage 2: Protocol and authentication test
Validate each planned integration method separately:
| Test Item | What to Check |
|---|---|
| HTTP | Whether an HTTP client connects normally |
| HTTPS | Whether TLS connects normally; whether certificate validation meets program requirements |
| SOCKS5 | Whether the appropriate client can establish a connection |
| Username/password | Whether system returns are clear for valid vs. invalid credentials |
| IP allowlist | Whether permissions behave as expected after changing the server exit |
| API extraction | Whether API return format, error codes, and parameters are stable |
Example configuration with placeholder parameters:
curl \
  --proxy http://username:password@proxy_host:port \
  --connect-timeout 10 \
  --max-time 30 \
  https://test_address
Replace username, password, and address in test commands with the project's actual configuration. In production, never commit sensitive credentials to code repositories or public logs.
Stage 3: Small-scale business test
After baseline connections work, test with requests closer to real business:
- Use the production program's request headers and timeout configuration.
- Use a small-batch task — don't start at maximum concurrency.
- Log success, timeouts, connection failures, and business status anomalies.
- Check whether returned content is complete, not just the status code.
- Continuously test the same resource — observe whether sessions persist.
- Cross-test different resources — judge whether problems concentrate in a specific region or node.
Stage 4: Stepped concurrency test
Increase concurrency in steps — don't ramp straight to the target ceiling.
| Stage | Recommended Action | Observation Focus |
|---|---|---|
| Single connection | Validate baseline configuration | Authentication, protocol, connectivity |
| Low concurrency | Close to actual minimum load | Response time, error types |
| Medium concurrency | Close to normal operating level | Timeouts, queuing, connection reuse |
| Target concurrency | Simulate formal operation | Stability, resource limits |
| Peak concurrency | Short-term validation within authorized limits | Limit notices, failure recovery |
Each stage should retain test time, concurrency parameters, and results — don't just keep the final conclusion.
What Criteria Judge an IP Proxy Test as Passed?
Passing isn't "occasionally connects" — it means key metrics continuously satisfy the project's acceptable range.
Use "hard thresholds + observation items" to judge.
Hard thresholds
Failing any one shouldn't lead to direct integration into formal tasks:
- Protocol incompatible with the program.
- Authentication method unusable in the production environment.
- Region-identification results don't match project requirements.
- Connections drop frequently with no clear retry or switching mechanism.
- Returned content is often incomplete.
- Billing method can't map to project request volume or traffic statistics.
- Usage scope, data origin, or access permissions cannot be confirmed.
Observation items
The following don't need unified numeric standards but should match project tolerance:
| Metric | Observation Method | Judgment Approach |
|---|---|---|
| Connectivity | Multiple consecutive request rounds | Whether clustered failure windows exist |
| Response time | Log connection, first byte, full response | Whether it affects business timeout settings |
| Stability | Continuous runtime testing | Whether periodic interruptions appear |
| Regional accuracy | Multiple exit-info identifications | Whether consistent with filter conditions |
| Session persistence | Set fixed sessions and repeat visits | Whether business state continuity holds |
| Error recovery | Simulate connection failures or resource invalidation | Whether auto-retry or switching works |
| Cost control | Compare against request-volume or traffic records | Whether usage cost can be accurately estimated |
| Log completeness | Check test and runtime logs | Whether anomaly origins can be located |
Final acceptance records can fall into three categories:
- Pass: all hard thresholds met; observation items match project requirements.
- Conditional pass: baseline capability met, but concurrency, region, or task scope needs limits.
- Fail: critical issues in protocol, authentication, region, stability, or compliance.
What Steps Does IP Proxy Integration Involve?
Formal integration starts with configuration isolation, then small-traffic validation, then gradually expanding usage scope.
Step 1: Establish independent configuration
Don't scatter proxy addresses, ports, and credentials across business code — centralize them in a configuration center or environment variables:
PROXY_HOST=proxy_address
PROXY_PORT=proxy_port
PROXY_USERNAME=username
PROXY_PASSWORD=password
PROXY_PROTOCOL=http
PROXY_TIMEOUT=30
PROXY_RETRY_LIMIT=2
Production environments should use permission controls — ordinary developer accounts shouldn't see full credentials directly.
Step 2: Encapsulate the proxy connection layer
Encapsulate proxy configuration as a standalone module; business code only calls the unified interface. This way, resource changes, timeout adjustments, or failover additions don't require modifying all business logic.
The connection layer should support at least:
- Unified configuration reading
- Connection timeout control
- Response timeout control
- Bounded retry
- Error type logging
- Resource switching
- Business request cancellation
- Sensitive-field masking
Step 3: Integrate into test environment
Validate in the test environment first:
- Whether single requests succeed.
- Whether returned business content is complete.
- Whether request logs match expectations.
- Whether real failure causes get recorded.
- Whether retries cause duplicate submissions.
- Whether connections release properly on timeout.
- Whether the program needs restart after swapping proxy resources.
Step 4: Small-traffic phased release
Don't switch all formal tasks at once — expand gradually:
| Phase Stage | Goal |
|---|---|
| Trial run | Validate configuration and business logic |
| Small-ratio tasks | Observe error types under real business |
| Single region or single project | Confirm regional and task fit |
| Expand concurrency | Validate resource limits and cost changes |
| Full integration | Enter routine monitoring and failure handling |
During phased release, keep the original network path or backup available — makes it easier to tell whether proxy chain or business code changes caused issues.
Step 5: Establish a rollback mechanism
After integration, you must be able to shut off or switch quickly. The rollback mechanism should include at least:
- One-click proxy configuration disable
- Switch to backup resources
- Reduce concurrency or pause new tasks
- Preserve recent runtime logs
- Record switch time, reason, and impact scope
Integration schemes without rollback capability aren't suitable for direct use in critical production tasks.
What Metrics Should Be Monitored After Launch?
Post-launch monitoring focuses on detecting anomaly trends — not just counting daily successes.
Build four categories of monitoring.
Connection monitoring
- Connection success rate
- DNS, TCP, or TLS connection errors
- Connection timeout count
- Connection drop count
- Retry count
Request monitoring
- Total request volume
- Successful request volume
- HTTP status code distribution
- Average and long-tail response time
- Empty or incomplete response count
Resource monitoring
- Proxy resource usage
- Request or traffic consumption
- Concurrent connection count
- Resource validity
- Error distribution across regions or resource groups
Business monitoring
- Whether key pages or endpoints return as expected
- Whether data fields show widespread missing values
- Whether task completion time extends abnormally
- Duplicate submission count for the same task
- Whether failures trigger correct manual or automated handling
Don't set only a single overall failure rate alert — split by region, protocol, resource group, and business task. Even when overall metrics look normal, a specific region or resource group may already be anomalous.
What Compliance and Security Boundaries Apply to IP Proxy Use?
IP proxies should only be used for authorized network access and legitimate business — not for bypassing access permissions or disrupting target systems.
Before project launch, confirm:
- The access target is a public page, public API, or authorized system.
- Collection content complies with site rules, contractual terms, and applicable laws.
- Request frequency, concurrency, and access time won't put abnormal pressure on the target system.
- Don't collect unnecessary personal sensitive information.
- Don't commit account passwords, tokens, or full proxy credentials to public code or logs.
- Set permissions on test data, task results, and access records.
- When anomalies occur, be able to pause tasks, preserve logs, and run human review.
When business goal, authorized scope, or data-handling method is unclear, pause integration first — complete approvals and technical boundaries before testing.
How to Handle Common Problems?
Most integration problems can be diagnosed by distinguishing five layers: protocol, authentication, region, resources, and business returns.
Q: Testing connects but the production program keeps timing out — what to check first?
Compare the test command and the production program on timeout configuration, connection-reuse pattern, DNS handling, and request headers. Then confirm whether production server exits, concurrency, and threading model match the test environment. Don't look only at single-request results — log connection time, time to first byte, full response time, and the timeout location separately.
Q: The proxy can access test addresses but business pages return incomplete content — is it necessarily a proxy issue?
Not necessarily. Check business request parameters, response compression, redirects, TLS validation, content parsing, and the target page's own return status. Reproduce with the same proxy, same request parameters, and same time window first, then compare against results without the proxy.
Q: The project needs to maintain login state — what to test with priority?
Prioritize testing session persistence, exit change cycle, cookie handling, connection reuse, and failure retry. If a retry might duplicate a business action, separate read requests from write requests in design to avoid duplicate operations from naive retry.
Q: How to choose between per-request and per-traffic billing?
Estimate per-request average response size, daily request volume, failed-retry volume, and task peaks, then convert to cost under both billing methods. Don't calculate only from theoretical request volume — leave consumption headroom for timeouts, retries, and anomalous responses.
Q: Should testing push concurrency straight to the production peak?
Not recommended. Start from single connection, step up to routine concurrency, then validate the peak within authorized limits. Log error types and response changes at each stage. If low concurrency is already unstable, pushing higher won't prove the resource suits the project.
Q: When the proxy fails after launch, should you swap resources first?
Preserve on-site information first, then switch. Log at least: occurrence time, task, region, protocol, resource ID, error type, and concurrent load at the moment. After logging, you can switch to backup resources per the preset strategy and separately re-test the original resource — this avoids misdiagnosing a business issue as a resource issue.
How to Produce the Final Selection Conclusion?
The final conclusion should specify applicable scenarios, limitations, test results, and launch actions — not just "usable" or "not usable."
Output the selection result in this format:
Project name:
Business scenario:
Authorized scope:
Target region:
Protocol used:
Planned concurrency:
Task duration:
Selected type:
Authentication method:
Test time:
Test environment:
Test conclusion:
Validated capabilities:
Known limitations:
Launch scope:
Monitoring metrics:
Failover plan:
Rollback conditions:
Re-test cycle:
A proper IP proxy selection result should answer four questions at minimum:
- Why choose this type?
- Which actual tests did it pass?
- Under what conditions should it not be used?
- How to detect problems after launch and switch in time?
Executing in the order "requirements confirmation, type matching, staged testing, phased integration, continuous monitoring" turns an IP proxy from a one-off purchase into a verifiable, manageable, rollback-ready project network component.