A data collection project integrating proxy IPs doesn't end when you drop the proxy address into the program. What actually affects stability includes task type, request frequency, exit switching method, authentication mode, timeout strategy, and exception handling.
If requirements aren't broken down upfront, you'll run into proxy-type mismatches, frequent request timeouts, session interruptions, excessive duplicate IPs, or hard-to-reconcile costs. So push things forward in five stages: "requirements confirmation, product matching, integration configuration, test validation, production maintenance."
Why Does Data Collection Need Requirements Confirmation First?
Confirm the collection task's access target and request characteristics first — only then can you judge which proxy product category is needed.
Log at least the following during requirements confirmation:
| Confirmation Item | Questions to Clarify |
|---|---|
| Data scope | Which public pages, endpoints, or business data are being collected? |
| Access region | Country, region, city, or carrier specification needed? |
| Request scale | Approximate requests per minute, per hour, per day? |
| Session requirement | Does each request need a fixed exit? How long does a single session last? |
| Concurrency pattern | Single-threaded sequential access, or multiple tasks in parallel? |
| Collection time | Only business hours, or continuous runtime? |
| Compliance boundary | Necessary authorization in place? Access frequency and data retention under control? |
Don't just write "need lots of proxy IPs" on the requirements form. "A lot" can't directly drive configuration — break it down into request volume, concurrency, IP rotation cycle, and per-session duration.
How Should Collection Tasks Be Split?
Batch short requests, continuous monitoring, and session-based collection don't have the same proxy IP requirements.
Batch short requests
Web scrapers, public document organization, and bulk corpus crawling typically show short per-request time, many access targets, and noticeable IP-usage variance. These tasks focus on extraction speed, IP rotation, and per-volume accounting.
Sustained requests
Sentiment monitoring, ad monitoring, and price monitoring require the program to run long-term. The focus shifts to unified integration entry, automatic switching, connection stability, and exception retry — suits prioritizing tunnel-type integration evaluation first.
Session-based collection
App big-data analysis, bidding data organization, and similar tasks may require relatively stable exits within the same session. Here, focus on verifying long-lived or dedicated type validity, region, concurrency, and authentication conditions.
Multi-project parallel
When multiple projects run simultaneously, save task config, auth info, logs, and statistics separately. Don't let all tasks share one indistinguishable parameter set — otherwise, after anomalies, you can't tell the impact scope.
What Conditions Should Be Verified When Choosing Proxy Products?
Product selection should focus on request cycle, exit stability, and integration method — not just resource count.
Verify at least these six items:
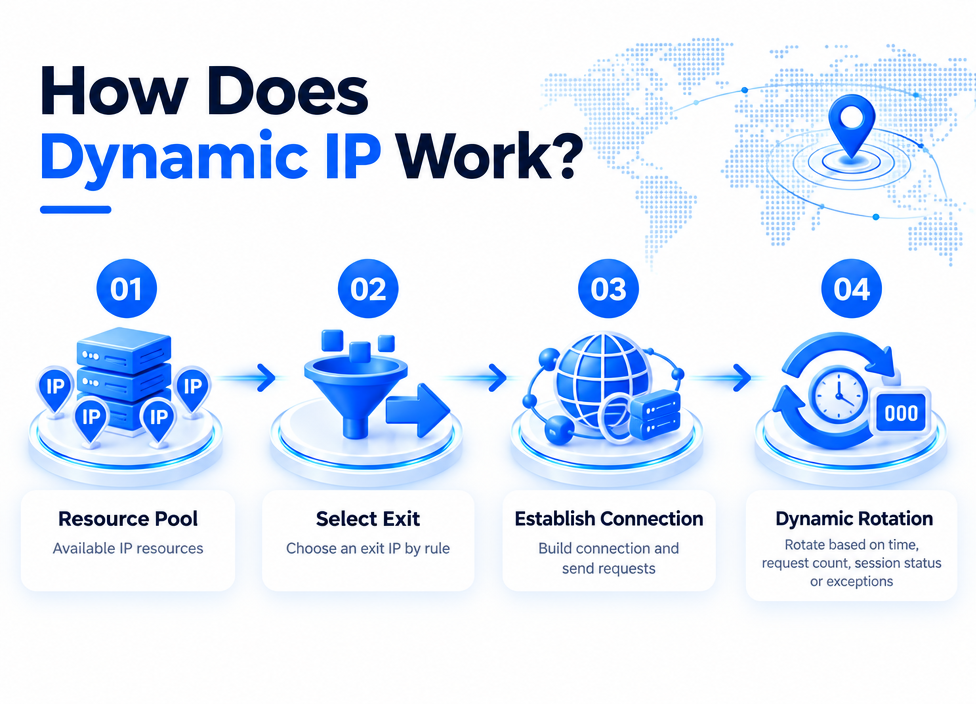
- IP validity cycle: specify whether IPs rotate per request, hold by time, or are actively extracted by the program.
- Protocol support: confirm HTTP, HTTPS, or SOCKS5 support, and check whether the program or runtime environment is compatible.
- Authentication method: common ones include username/password, IP allowlist, API key, or combined auth.
- Regional filtering: confirm region is country-level, city-level, or carrier-level, and whether dynamic adjustment is supported.
- Billing unit: distinguish per-request, per-traffic, per-time, per-concurrency, or per-plan billing.
- Technical boundaries: confirm concurrency count, extraction frequency, validity period, endpoint return format, and error codes.
If the task only needs short-term exit rotation, evaluate short-lived types first. If the program needs sustained requests with server-side switching, evaluate tunnel types. If the task requires exit persistence within a session, further verify long-lived or dedicated types.
What Configuration Needs to Be Prepared Before Integration?
The more complete the config items, the easier troubleshooting is later.
Build a proxy configuration table containing at minimum:
Task name:
Target region:
Proxy protocol:
Proxy address:
Proxy port:
Authentication method:
Username or key:
IP rotation method:
Connection timeout:
Read timeout:
Max retry count:
Concurrency ceiling:
Log location:
Don't just copy timeout and retry parameters from examples. Start with connection timeout at 3–10 seconds, read timeout at 10–30 seconds, and max retry at 1–3 — then adjust based on actual target and network conditions.
When retrying, distinguish connection failures, proxy authentication failures, target response timeouts, and business-status anomalies. Retrying all errors unconditionally can amplify request volume and mask real failures.
How Should API Integration Be Completed?
API integration typically has three steps: get proxy parameters, write program configuration, and validate return results.
Step 1: per the endpoint documentation, submit region, count, protocol, or validity parameters to get proxy address, port, and authentication info.
Step 2: convert the return into the program's configuration format. Example using a common HTTP request:
import requests

proxy = "http://username:password@proxy_host:port"

response = requests.get(
    "https://example.com/data",
    proxies={
        "http": proxy,
        "https": proxy
    },
    timeout=(5, 20)
)

print(response.status_code)
print(response.text[:200])
Step 3: log each request's status code, response time, proxy identifier used, and exception type. Don't just print "success" or "failure" — otherwise, you can't tell whether the problem comes from the proxy, target address, or program itself.
If the endpoint returns JSON, also save request time, region parameter, IP validity, and return error codes. This lets you compare success rates and timeouts across different configurations after testing.
How to Validate Configuration Before Launch?
During testing, lock target, request method, concurrency, and time window — don't mix different conditions.
Test in this order:
- Send a baseline request with a single proxy, confirm authentication and protocol work.
- Send a batch of low-concurrency requests consecutively, observe connection timeouts and response times.
- Raise to planned concurrency range, log success rate and error types.
- Verify whether IP rotation matches expectations, check duplicate-IP ratio.
- Test retry and re-fetch logic after proxy failure.
- Check whether logs can correlate task, request, and proxy information.
- Run a small-scale trial with real business requests.
Test records should include at least business success rate, connection timeout rate, average response time, IP switch time, duplicate-IP ratio, and exception retry count.
A usable proxy IP doesn't mean the business request will succeed. Target page structure, request method, access frequency, network environment, and program parsing logic can all affect the final result.
How to Maintain Proxy Configuration During Runtime?
Production environment should separate proxy config, business code, and monitoring metrics.
After launch, focus on:
- Whether proxy authentication failures suddenly increase
- Whether connection timeouts cluster in a specific region or time window
- Whether duplicate-IP ratio exceeds task-acceptable range
- Whether per-request retry count keeps rising
- Whether actual consumption is noticeably above projected usage
- Whether an anomaly in one task affects other tasks
Manage proxy address, port, and keys through environment variables or a configuration center — don't commit them directly to public code repositories. Use different configurations for different environments; test and production shouldn't share keys.
When task target, request volume, or session requirements change, re-evaluate proxy type. Don't assume the same configuration applies long-term to all tasks just because initial testing succeeded.
Summary
when integrating proxy IPs into data collection, confirm task, request, session, and compliance boundaries first, then complete product matching, parameter configuration, fixed-condition testing, and production monitoring. Validating step by step is safer than directly scaling up concurrency.
FAQ
Q: Does data collection always need proxy IPs?
Not necessarily. Whether to use proxy IPs depends on task scale, access region, concurrency pattern, session requirements, and target-side public rules. Small-scale, low-frequency tasks with clear authorization boundaries can evaluate direct connection first; when tasks need multi-region access, continuous runtime, or per-project management, then evaluate proxy integration.
Q: What's the difference between short-lived proxies and tunnel proxies?
Short-lived proxies usually require the program to actively fetch the proxy address — suits batch short requests and well-defined IP extraction tasks. Tunnel proxies typically provide a unified entry with server-side exit switching — suits sustained requests. Final choice also depends on whether sessions need fixed exits, billing method, and concurrency requirements.
Q: Why do business requests still fail when the proxy connection succeeds?
A successful connection only means the program can reach the proxy — it doesn't mean the target business returns valid content. Failure causes may also include target response timeout, request parameter errors, page structure changes, mismatched access frequency, or program parsing anomalies. Judge together with status codes, response bodies, and logs.
Q: Which metrics should testing log?
Log business success rate, connection timeout rate, average response time, IP switch time, duplicate-IP ratio, and exception retry count. If controlling cost, also log request volume, traffic, or concurrency usage — and keep it consistent with the product's billing unit.
Q: Can proxy keys be written directly into the program?
Not recommended. Keys should be injected through environment variables, secrets management tools, or a configuration center — code only reads variables. If you must temporarily write to local config, restrict file permissions and check for real credentials before committing code.